MakeBoxExplore tools

DeepSeek
Super-agent.
Less managing.
More building.

The open-source research prototype asks a bigger question than “can AI code?” Can it coordinate the work without making you manage every conversation?

Explore the architecture

One request. Parallel work. A clear handoff.

MakeBox EditorialNovember 1, 20268 minute read
RouterOne point of coordination
Reproduce a bugIsolated task context
Respond to reviewA separate work session
Build a featureProgress in parallel

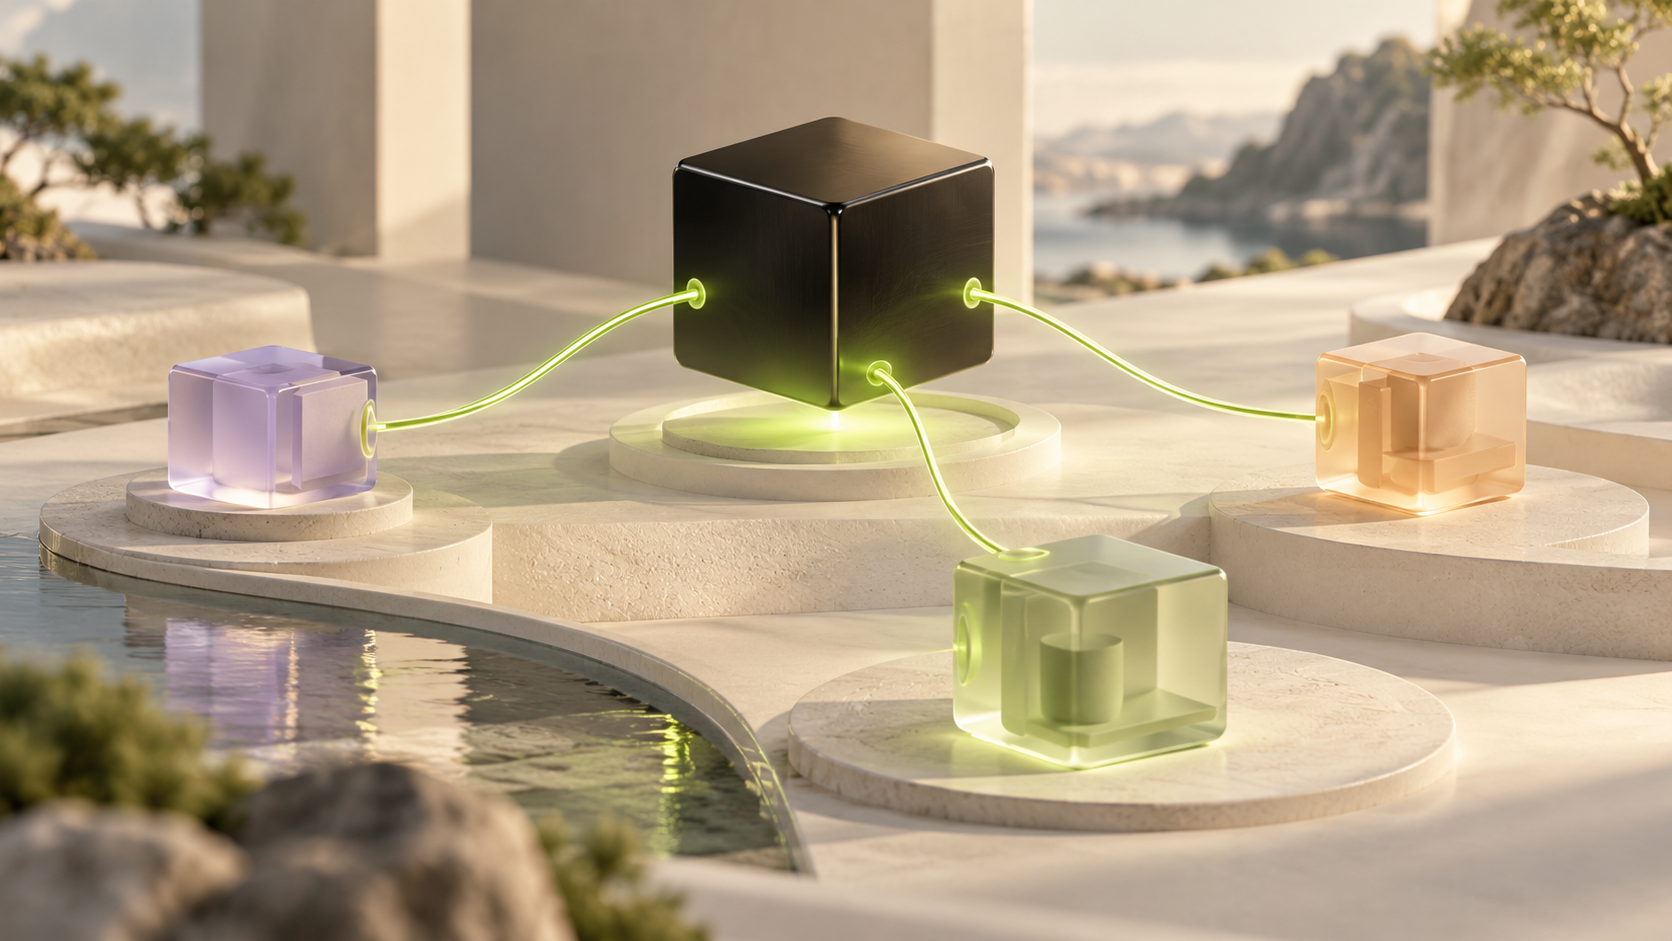
Editorial illustration of the Router–Worker design. Not a live agent.

Conceptual illustration of a central coordinator connected to three glass task modules

Follow the work, not the windows.

MAKEBOX / EDITORIAL ILLUSTRATION
AI-generated conceptual illustration by MakeBox. Not a product screenshot or evidence of a real event.
01 — The shift

Your attention is
part of the system.

Imagine three requests arriving together: a failing test, a review comment and a small feature. The difficult part is not only solving each request. Someone must remember the context, decide what matters and bring the right result back to the right conversation.

That coordination burden is the interesting problem behind DeepSeek Super-agent. The public dsh-superagent-prototype is an MIT-licensed bundle for DeepSeek Harness, scoped to a GitHub repository with optional Feishu input. It creates work items, uses separate task sessions and directories, and reports back where the request originated.

The October 31 code release is a research reference. The team's English design article appeared on November 1. It describes a broader architecture than the published prototype implements. This is not a new model checkpoint or a finished autonomous employee.
Follow one request.

SCROLL TO EXPLORE · SWIPE ON MOBILE

Skip visual story ↘
01 / ARRIVAL

One request.
A clear scope.

A new request enters the routing path. The permission boundary still matters.

Conceptual AI-generated editorial illustration
02 / EXECUTION

Separate contexts.
Parallel progress.

The design gives individual tasks their own Workers, keeping execution away from the global conversation.

03 / HANDOFF

Bring the result
back to people.

A completed task needs an understandable outcome, evidence and a clear next decision.

Work.
Evidence.
Decision.

Editorial explanation · illustrative motion, not live activity. The sourced figures below remain unchanged.

02 — Architecture

One conversation.
Several things moving.

The design separates coordination from execution. A Router handles dispatch; Workers carry out individual tasks. Follow-up events can go directly to a subscribed Worker. Select a path to see the distinction.

How a routing path stays in motion

Dispatch
Execute
Review

Looping editorial illustration. Not a running agent or a benchmark animation.

Interactive editorial explanation based on the team's design article, sections 2–3. It illustrates routing, not execution of real code.

03 — Benchmarks, with context

Faster completion.
A larger token bill.

These are the team's preliminary scheduling experiments—not a code-quality leaderboard. Work was simulated. Switching metrics makes the trade-off visible instead of hiding it behind a single headline.

46.8%

Lower p95 completion time versus the neutral-prompt single-session baseline. Calculated from 29.5 → 15.7 minutes. Not a measured improvement in coding accuracy.

Swipe the table to see all columns.

Reported results · five runs per configuration · lower completion time is better
Configurationp50 / minp95 / minCache reads / run
Super-agent12.415.723.2M tokens
Without pass-through12.615.531.8M tokens
Single session · neutral prompt20.429.56.1M tokens
Single session · delegation-first13.829.010.8M tokens

Source: DeepSeek Harness design article, §7.1. Values are vendor-reported and were not independently reproduced by MakeBox. Cache reads are not total tokens or dollar cost.

Our reading: delegation needs an explicit place in the system. A prompt that merely encourages it may still leave the main session doing the work. But more parallel context can also mean more consumption. Here, Super-agent used about 3.8 times the cache-read tokens of the neutral baseline. A real evaluation should track useful accepted changes, total cost and reviewer effort together.

04 — Read the fine print

A design is not
a shipping checklist.

The most useful comparison is between what the research describes and what you can responsibly claim about the public code. Comparing brand names with simplified “reactive vs. autonomous” labels would hide too much.

Swipe the table to see all columns.

QuestionWhat the evidence supportsWhat it does not establish
Is it open source?The prototype is published under MIT.A supported, production-ready service.
Can it act proactively?Policy-controlled admission of inferred work.Permission to act on every message.
Are Workers isolated?Separate task contexts and working directories.A security sandbox merely because a directory is separate.
Is it always online?Persistence is a goal of the broader architecture.A local installation continuing when its host is off.
Does it beat Claude Code or Codex?The experiment compares four scheduling designs.A direct competitive coding benchmark.

The authorization documentation is particularly important. Incoming content cannot rewrite the host's permissions. Subscriptions deliver context without granting new authority. That distinction is worth preserving in any real workflow: “the agent saw this request” and “the agent may carry it out” are different states.

For a pilot, choose a disposable repository, narrowly define who may request work, and keep review and merge decisions visible. Those are our evaluation recommendations, not a claim that the prototype eliminates operational risk.

From the team

Read the original announcement.

The official article includes architecture diagrams, examples from the team's internal workflow, experiments and unresolved problems. Read it alongside the repository—not as a promise that every design element ships today.

Open the official article
Cover artwork for the DeepSeek Harness team's Super-agent design article
Official article cover · DeepSeek Harness. External media; opens the original announcement.
05 — The MakeBox take

Judge the work it finishes.
And the attention it gives back.

01

Count interventions.

Record how often someone must restate context, redirect a task or recover a stalled session. A faster agent that needs constant rescue may not save your team time.

02

Follow the whole cost.

Include model usage, retries, infrastructure and human review. Cache-read tokens reveal one part of this story, not the complete price of a finished change.

03

Keep ownership clear.

Make the request, permission, work item and final review traceable. Parallel execution is valuable when people can still explain what changed and why.

For small businesses, the transferable idea is straightforward: use automation to carry context and prepare work, then put clear decisions in front of a person. The immediate opportunity is a better handoff between people and tools. Whether this prototype is the right implementation should be established through a bounded test—not assumed from a launch headline.

Turn AI news into practical skills.

Explore MakeBox School for practical AI training, or see our services for a separately scoped automation project.

Explore MakeBox School

Discuss an automation project

Questions worth asking.

Is Super-agent the same as Hermes?

No. This article covers DeepSeek's dsh-superagent-prototype. Hermes Agent is a separate project from Nous Research.

Do the benchmarks measure real coding ability?

No. The study used a time-consuming stand-in for coding work. It evaluates scheduling under a synthetic event stream, not correctness of generated code.

Can I treat the published code as the internal system?

No. The README explicitly says the published version differs from the internal version and does not implement every direction in the design article.

Sources & editorial notes

  1. Official repository and README — scope, license and prototype limitations.
  2. Exploring Super-agent Design — DeepSeek Harness — English machine translation, November 1; architecture, experiments and official artwork.
  3. Original Chinese article — linked for reference; this page relies on the team's accessible English version.
  4. Authorization model — permissions, admission and subscriptions.

Prepared November 1, 2026. MakeBox analysis; no hands-on benchmark or endorsement claimed. Interactive diagrams are explanatory illustrations. Published November 1, 2026.

What the test actually measures.

Each configuration ran five times on roughly 300 messages, including about 20 work requests. Coding was replaced by a tool that consumes time. Message intervals and work durations were scaled to one quarter; model-call times were not.

Completion time runs from a work request to its result message. p95 describes the slower end of the distribution. Cache reads include all sessions and are not the complete monetary cost.

These figures support a discussion of coordination. They do not prove code quality, real-world productivity gains or superiority to another commercial coding agent.

Read §7 of the original article